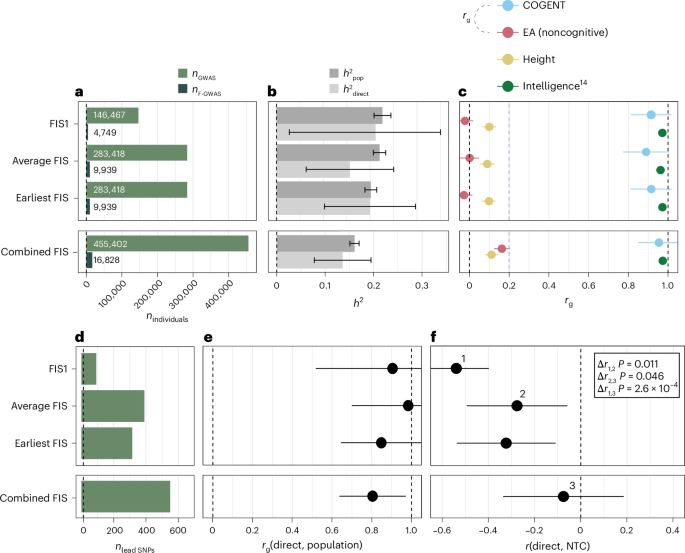
Imputation of fluid intelligence scores reduces verification bias and increases the power of common and rare variant analyzes

Ethics monitoring
UK Biobank obtained ethical approval from the NHS North West Center Research Ethics Committee (reference 11/NW/0382) and approved the use of data for this study.
Sample selection
We performed all analyzes only on genetically clustered individuals with European ancestry (n = 455,943). This was inferred by first projecting the principal components (PCs) of 1000 Genomes onto UKB participants and excluding participants who did not cluster with the European populations of the 1000 Genomes Project. After this, another principal components analysis was conducted to capture ancestry differences within genetically more homogeneous individuals of European/British ancestry.72.
FIS score transformations
To correct for age decline in FI over time and scale differences between FI tests, we transformed the FIS measures. For each FIS separately, we ran a regression model: FIS ~ age + age2extracts the residuals and adds the intercept to account for differences in means between measurements. The age used was the age of the participant at the time of the respective measurement, which was either obtained from the UKB variable “age attended assessment center” (data field 21003) or approximated from “when the FI test is completed” (data field 20135) using the participants’ year and month of birth.
For the online measures (FIS4 and FIS5), we performed an additional transformation, setting all scores between 14 and 13, before running the regression model. This broadly aligns the scales of the online measures (14 questions) with those of the in-person test (13 questions; additional note 1).
Imputation
SoftImpute
The R SoftImpute package73 was used to impute FIS. SoftImpute is a matrix completion algorithm that approximates missing values by identifying and exploiting patterns in the available data. To do this, it minimizes an objective function composed of two terms: (1) the distance between observed entries in the observed and imputed data matrices according to the Frobenius norm, and (2) the product of a tuning parameter. λand the sum of the singular values of the imputed data matrix. Intuitively, this means that the algorithm fills in missing values in a way that minimizes the rank of the imputed data matrix, thus favoring low-dimensional structure over complexity. This starts with an initial estimate of the missing values, then iteratively refines that estimate by applying a soft-threshold singular value decomposition on the full matrix. The main parameters specified in SoftImpute are rank and λ . Ranking determines the maximum number of factors the method uses to represent data and should always be set to at most Nvariables − 1. λ controls the degree of smoothing applied during imputation. A top λ aims to reduce the complexity of the model, making it less sensitive to noise and more prone to overlooking nuances. Ideally, λ is set to be slightly lower than the defined rank.
Variable selection
Our imputation strategy underwent several refinement phases (additional note 3), one of which concerned the selection of imputation variables. Here we describe the criteria used for the initial selection and the steps taken to refine this set.
Initial selection
We first selected 152 UKB phenotypes from those collected during the initial assessment center visit that had at least nominally significant correlation (P. < 0.05) with FI observed, focusing on FIS1 because it had the largest sample available at the time. For continuous phenotypes, we chose those with absolute phenotypic correlation (|rpheno|) with FIS1 0.05 at a significance level of P.<0.05. Categorical phenotypes were first classified into ordinal and nominal types and then further evaluated. For ordinal phenotypes, we checked if the values could be interpreted as a quantitative variable, rearranged them if necessary and then kept those with |rpheno| 0.05. We converted the nominal phenotypes with ncategories in n− 1 binary variables, after which we calculated the rpheno between each of these binary variables and FIS1. We only included variables with two or more categories having |rpheno| 0.1. We excluded phenotypes that are part of any FIS measure. In total, we selected 90 continuous phenotypes, 59 ordinal phenotypes and 3 nominal phenotypes (Supplementary Table 4). For the three nominal phenotypes, we selected the categories with a strong correlation with FIS1 (|rpheno| 0.1), encoded them as additional binary phenotypes and removed the original phenotypes, ultimately leading to a set of 154 variables used as the initial set. Finally, we coded all missing values (e.g., “prefer not to answer” or “unknown”) as NA. Based on the resulting 154 phenotypes, we performed an imputation with the SoftImpute parameters: rank = 150, λ= 120.
Final selection
In our final selection, we narrowed the initial selection of variables to phenotypes that more specifically correlate with the cognitive signal. To examine which phenotypes meet this criterion, we derived a GWAS of the “non-cognitive component of imputed FIS” (NonCog-iFIS) from our first FIS imputation. To do this, we applied a GenomicSEM model (Supplementary Fig. 7) for GWAS by subtraction, as applied in ref. 30. GenomicSEM is an R package for fitting structural equation models to GWAS summary statistics. In subtraction GWAS models, a model is fitted that includes two phenotypes (GWAS) and two latent factors. The first latent factor represents the commonalities between the phenotypes by regressing the two phenotypes on this latent factor. The second latent factor includes genetic variance specific to one of the phenotypes. This is achieved by regressing the remaining genetic variance for the phenotypes on the latent factor after regressing the variance captured in the first latent factor. Subsequently, the two latent factors can be regressed on individual SNPs to obtain GWAS. In our analysis, we ran a subtraction GWAS model using intelligence as mentioned in ref. 14and in our first iteration, FIS values imputed as phenotypes. The model allows us to capture genetic variance unique to this imputed FIS in the latent factor “NonCog” and then regress individual SNPs on this factor to obtain the NonCog-iFIS GWAS.
We then calculated the genetic correlations between each of the 154 imputation variables and intelligence in ref. 14 and the derived NonCog-iFIS GWAS (Supplementary Table 4). We retained phenotypes in the final selection if the absolute genetic correlation was stronger with intelligence than with NonCog-iFIS (Supplementary Fig. 8), resulting in the selection of 82 phenotypes.
For imputations using the final variable selection, we adjusted our SoftImpute parameters (rank = 80, λ= 70) due to the reduced number of selected phenotypes. We also explored the effects of different imputation parameters on imputation accuracy, but found that rank = 80 and λ= 70 achieved the highest imputation accuracy (Supplementary Fig. 9, left).
Remove outliers
After each imputation, we identified and removed outliers using the criterion:
$${X_{i}}\notin \left(\overline{X}-3\sigma ,\,\overline{X}+3\sigma \right)$$
Or XI represents an imputed score, \(\overline{X}\) represents the average of the measured score and σrepresents the standard deviation of the measured score.
In other words, we removed individuals whose imputed score was greater than 3 SD from the mean of the observed scores. This results in slightly different sample sizes across imputation approaches (Supplementary Table 6).
Accuracy assessment
To evaluate the accuracy of imputation, we randomly selected 50,000 participants as the evaluation set. We introduced “synthetic disappearance” by setting FIS measures for these participants to be missing. After imputation, we examined the Pearson correlation between the imputed FIS values and the original measurements in our evaluation set and defined this correlation as the accuracy of the imputation. Only participants with the targeted FI measure were included in the calculation of the accuracy of each FI measure (Supplementary Table 5).
We also examined whether imputation was more accurate in different parts of the phenotypic distribution. We categorized the observed values from the evaluation set into low, medium, and high terciles and then examined imputation accuracy within each tercile using the same strategy as above. We found that imputation accuracy was higher in the low and high terciles than in the middle tercile (Supplementary Fig. 9, right).
Combination of measured and imputed FIS
The combination of imputed and measured FIS was performed by mega-analysis in all approaches. Prior to mega-analysis, imputed and measured values were scaled separately to have a mean of 0 and a standard deviation of 1. Although this could in principle bias associations, the resulting per-SNP bias accommodates differences in allele frequency between measured and imputed individuals, which are likely negligible (see Supplementary Note 2 – Mega-analysis recovers population effects under calibrated imputation (Note 10) for further discussion). We also evaluated the combination of imputed and measured values through meta-analysis (Supplementary Note 4 and Supplementary Table 6).
GWAS
For GWAS, we used REGENIE34 (v4.1) stage 1 and stage 2 on the UKB search analysis platform. For step 1, we used genotyped SNPs from the UKB 22418 data field that passed standard quality control (missing ≤ 0.1, MAF ≥ 0.01, Hardy-Weinberg equilibrium). P.≥ 1 × 10⁻¹⁵). Individuals with a missing genotype of 0.1 were excluded.
In step 2, we analyzed the imputed SNPs from the UKB 22828 data field that are part of the Haplotype Reference Consortium.74 and pass quality control in unrelated European individuals (lack< 0.05, MAF >0.001, Hardy-Weinberg equilibrium P.1 × 10−10). To obtain the heteroskedasticity-robust standard error estimator in REGENIE, we specified a dummy interaction covariate and set ‘–rare-mac 0’ to force the use of the robust estimator for all SNPs. The dummy interaction covariate was generated to be a random standard normal variable.
The covariates (‘-–covarFile’) included in both stages were 25 genetic PCs that capture ancestry differences within European individuals72age (at the time of the respective FIS measurement), age2age × sex, age2× gender and the chart used to measure each…
Gn Health