
Human participants and cohorts
All samples analyzed in this study were collected using protocols approved by the Institutional Review Boards (IRBs) of their respective centers. Collection centers included Stanford University, Stanford Health Care, and Veterans Affairs Palo Alto (VA Palo Alto) Health Care System. BLCA cases were collected under IRB 55427. Control cases were collected under IRB 55427, 12597, or 18225. RCC samples were collected under IRB 12597. Prostate cancer samples were collected under IRB 49693. All participants provided written informed consent for the use of their clinical data and biological samples for research purposes. A total of 683 urine samples were collected from 515 individuals. Clinical and demographic characteristics such as age, gender and smoking history of participants are shown in Supplementary Table 1 and consent was obtained to publish clinical and demographic characteristics. Sexual and smoking history was self-reported and identified from medical records. Participants were not compensated for their participation in this study. Risk stratification was performed using the American Urological Association risk classification system, based on factors such as grade, stage, tumor size, and presence of carcinoma in situ.61.
Cancer cohorts
Patients with BLCA, PRAD, or renal cancer enrolled at Stanford University or VA Palo Alto.
Non-cancer cohorts
Individuals who were asymptomatic, had hematuria, or had lower urinary tract symptoms such as frequent urination, difficulty urinating, or discomfort during urination were enrolled at Stanford University or VA Palo Alto.
Validation cohorts
BLCA patients and cancer-free controls enrolled at Stanford University or VA Palo Alto but not used for model training.
Extraction, quantification and preparation of formalin-fixed paraffin-embedded tumor libraries
To compare tumor BLCA RNA versus urinary cfRNA and UROMOL/BRS subtype analyses, hematoxylin and eosin-stained sections from formalin-fixed, paraffin-embedded (FFPE) bladder tumor blocks were annotated by a pathologist to identify tumor-containing regions. BLCA grade and stage for each BLCA patient were obtained from clinical pathology reports and notes. Punches were performed on FFPE blocks targeting regions containing tumor tissue and RNA was extracted using the CELLDATA DNAstorm/RNAstorm 2.0 combo kit (Biotium) according to the manufacturer’s recommendations with minor modifications. The resulting eluate was incubated with 28 U of DNase I (RNase-Free DNase Set, Qiagen) for 30 min at room temperature to remove DNA. RNA was then isolated using the Zymo RNA Clean & Concentrator kit and stored at -80°C. RNA concentration was quantified using Nanodrop or quantitative PCR (qPCR). For library preparation, 100 ng of RNA was introduced into the library preparation. For samples containing less than 100 ng of RNA, all extracted tumor RNA was used for library preparation (range 25–100 ng). Double-stranded complementary DNA (cDNA) was synthesized from tumor RNA using the NEBNext Ultra™ II RNA First-Strand Synthesis Module and Non-Directional Second-Strand Synthesis Module (New England Biolabs). The double-stranded cDNA was treated with 100 U of S1 nuclease (Thermo Fisher) for 30 min at room temperature to hydrolyze the single-stranded regions. The KAPA Hyper Prep kit (Kapa Biosystems) was used to prepare the libraries for sequencing, following the manufacturer’s instructions with slight modifications as previously described.62. Capture of the entire coding transcriptome was performed using the Twist Biosciences Comprehensive Exome Hybridization kit, following the respective manufacturer’s instructions. Captured libraries were sequenced using 2 × 150 bp paired-end reads on Illumina HiSeq4000 or NovaSeq6000 instruments. For tumor FFPE samples captured using the Fully Encoding Transcriptome Capture Panel, we targeted approximately 30 million read pairs.
Urine collection and processing
The first empty urine samples were collected before any instrumentation in empty 120 ml urine collection cups (with or without subsequent addition of ethylenediaminetetraacetic acid to a final concentration of 5 mM) or Norgen urine collection and stabilization cups. Within 24 hours, the urinary supernatant was isolated by centrifugation at 2000°C.g for 10 minutes. Urine supernatant was stored at −80 °C until isolation of cell-free nucleic acid.
cfRNA extraction and DNA digestion
Q-Sepharose resin method
Cell-free nucleic acids were extracted from urine using a previously published protocol26 optimized for urinary extraction of cfDNA. The resulting eluate was incubated with 14 U of DNase I (RNase-Free DNase Set, Qiagen) for 30 min at room temperature to digest the DNA. The digested eluate was purified using the Zymo RNA Clean & Concentrator kit and stored at −80 °C.
Standard QIAamp method
Cell-free nucleic acids were extracted from urine using a previously published protocol62. The resulting eluate was incubated with 14 U of DNase I (RNase-Free DNase Set, Qiagen) for 30 min at room temperature to digest the DNA. RNA was purified using the Zymo RNA Clean & Concentrator kit and stored at −80°C.
Modified QIAamp method
Cell-free nucleic acids were extracted from urine using the miRNA protocol of the QIAamp Circulated Nucleic Acid kit (Qiagen (range 1–20 ml)) with slight modifications. Modifications include scaling the reagents proportionally to fit 4 ml of urine, increasing the lysis incubation time from 30 minutes to 60 minutes, and performing a double elution of the column to maximize RNA yield. The resulting eluate was incubated with 14 U of DNase I (RNase-Free DNase Set, Qiagen) for 30 min at room temperature to digest the DNA. The digested eluate was purified using the Zymo RNA Clean & Concentrator kit and stored at −80 °C.
Assessment and quantification of cfRNA size
The size distribution of cfRNAs in urine was analyzed using the Agilent Bioanalyzer RNA 6000 Pico chip. Real-time quantitative polymerase chain reaction was used for cfRNA quantification. An RNA-targeted amplicon was designed and generated by Elim Biopharmaceuticals to span the boundary between exons 1 and 2 in the housekeeping gene POLR2A (Forward 5′-TGAGTCCGGATGAACTGAAGC-3′, Reverse 5′-CCCTCAGTCGTCTCTGGGTA-3′). A pair of DNA-specific primers was designed to cover a 78-bp transcriptionally silent region of chromosome 12 (Forward 5′-TACGGTTGGTCCTTTCTTCG-3′, Reverse 5′-TTTCCTTTGGGTCTGAATGC-3′). Reverse transcription was first performed using the High Capacity cDNA Reverse Transcription Kit (Applied Biosystems). qPCR was then performed using 2X Power SYBR Green PCR Master Mix (Thermo Fisher Scientific) on Applied Biosystems 7500 Fast Real-Time PCR or QuantStudio 7 Pro instruments. Universal Human Reference RNA (Thermo Fisher Scientific) was run in parallel to generate a standard curve, and cfRNA concentrations were calculated by comparing the POLR2A Ct value of the sample to the standard curve. If DNA was detected using the DNA-specific primer, DNA digestion, cleanup, and quantification were repeated.
Preparation and sequencing of the cfRNA library
uRARE-seq
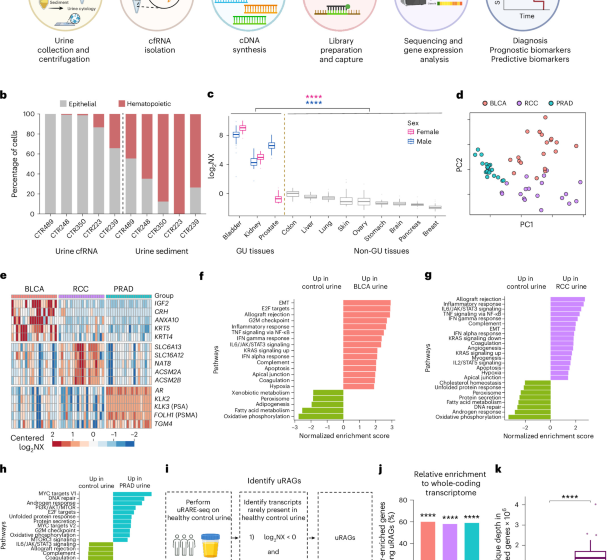
We targeted an input mass of 500 pg of cfRNA. For samples containing less than 500 pg, all extracted cfRNAs were used for library preparation (range 8–500 pg). Double-stranded cDNA was synthesized from cfRNA using the NEBNext Ultra™ II RNA First-Strand Synthesis Module and Non-Directional Second-Strand Synthesis Module (New England Biolabs). Double-stranded cDNA was treated with 100 U of S1 nuclease (Thermo Fisher) for 30 min at room temperature to hydrolyze incomplete (single-stranded) regions. The KAPA Hyper Prep kit (Kapa Biosystems) was used to prepare the libraries for sequencing, following the manufacturer’s instructions with slight modifications as previously described.62. Capture of the entire coding transcriptome was performed using the Twist Biosciences Comprehensive Exome Hybridization kit, following the manufacturer’s instructions. Monoplex capture using the uRAG capture panel (see “uRAG-centric capture panel design” for details) was performed using the Twist Biosciences hybridization kit (Supplementary Table 3). Captured libraries were sequenced using 2 × 150 bp paired-end reads on Illumina HiSeq4000 or NovaSeq6000 instruments. For urine samples captured using the Full-Coded Transcriptome Panel, we targeted approximately 30 million read pairs. For urine samples captured using the uRAG panel, we targeted 50-60 million read pairs.
Mapping, deduplication and quality control for uRARE-seq and tumor FFPE RNA
FASTQ files were demuxed using a custom pipeline as previously described62. Fastp (v0.20.0) was used to trim the first 10 bases from the 5′ end of read 1 and the 3′ end of read 2 and to remove low quality or short (<35 bp) read pairs from each sample. The remaining high-quality reads were aligned to the reference transcriptome (GENCODE v27) and the human genome (hg19) using STAR 2-pass63 (v2.7.0). PCR duplicates were removed from transcriptome- and genome-aligned files using a custom barcoding approach. Deduplicated reads were used for gene-level expression estimation using RSEM (v1.2.28)64.
Quality control was assessed using the RNASeQC package (v2.3.5), focusing on read mapping quality, mapping rates, and rates of exonic, intronic, intergenic, and ribosomal RNA reads. Additionally, DNA contamination was estimated by calculating the percentage of reads corresponding to intronic sequences out of the total number of reads corresponding to exonic sequences.
Normalization of gene expression
Expected RSEM counts for captured genes were used for expression analyzes (tximport R package v1.22). Counts were first normalized using the TMM method, which accounts for sample-to-sample variation in library size and transcriptome complexity (EdgeR R package v3.36). Log-transformed and normalized expression values are called “log”.2NX (normalized expression)’.
Differential gene expression analysis
Differential gene expression analysis was performed using DESeq265 (DESeq2 R Package v1.34). GSEA was performed using the fgsea R package (v1.20). GSEA was…
Gn Health